Why Lambda Architecture exists
There is a basic dilemma that many data platforms have to face: business teams on the one hand want quick answers (within seconds) and on the other hand want to be sure that the answers are correct (and this means using complete historical data). When you use only batch pipelines you obtain accuracy but at the cost of long waiting times. When you use only streaming pipelines you achieve speed but risk receiving late events, duplicates, and changing business rules.
Lambda Architecture was presented as a practical solution for achieving both of these objectives; it divides the processing work into two separate parallel pathways—the batch and the stream—and then combines the results from these pathways when querying. For people in Bangalore who are studying modern data engineering concepts as part of their data science courses, Lambda provides a helpful pattern to grasp since it makes the trade-offs involved in real-world pipelines clearer.
The three layers at a glance
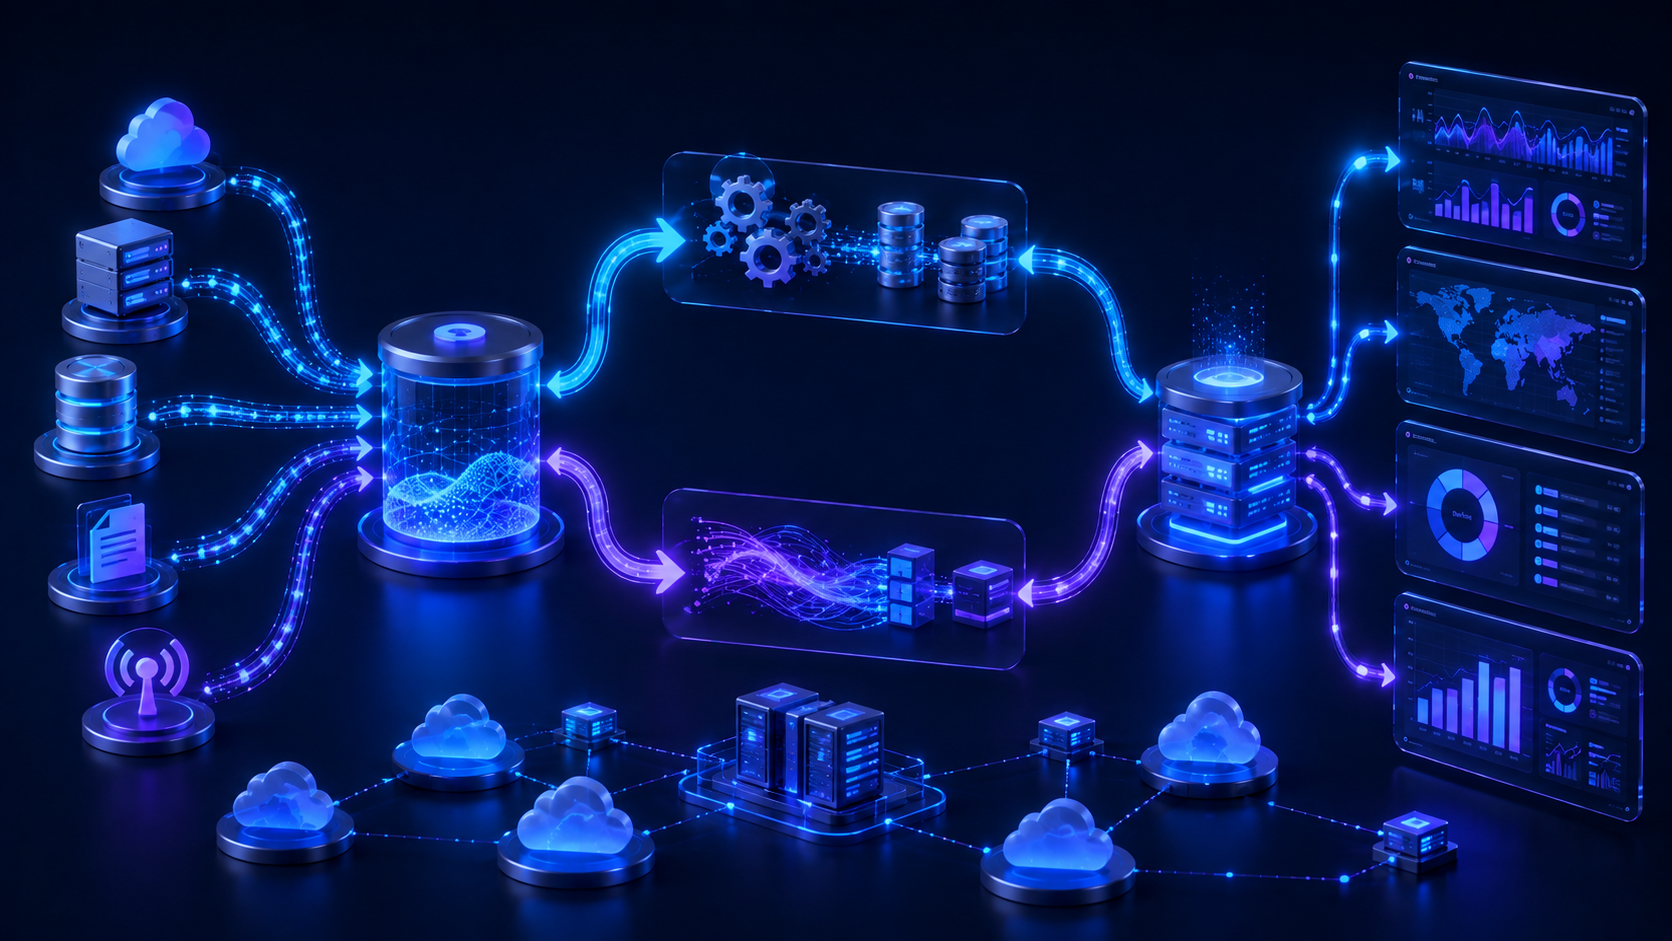
Lambda Architecture is typically explained with three layers:
1) Batch layer (the “truth builder”)
The batch layer holds an immutable, append-only master dataset (raw events) and periodically recomputes accurate views from scratch (or almost from scratch). The essential principle here is recomputability: whenever changes to the code are made or data quality problems are identified, the jobs can be rerun on all the historical data in order to rebuild the correct results.
What it’s good at
- Producing consistent, accurate aggregates
- Handling complex transformations and joins
- Supporting backfills when logic changes
Where it struggles
- Higher latency (minutes to hours)
- Operational cost when recomputation is heavy
2) Speed (stream) layer (the “freshness booster”)
The speed layer produces low-latency updates by processing the new events as they arrive, generally concentrating on incremental computations rather than full recomputation.
What it’s good at
- Near real-time dashboards (seconds)
- Monitoring and alerting (fraud spikes, system health)
- Quick features for personalisation (recent clicks)
Where it struggles
- Late or out-of-order events
- Exactly-once guarantees can be difficult depending on tooling
- Stream logic can get complex over time
3) Serving layer (the “query interface”)
The serving layer provides precomputed views in order to enable fast queries; in a traditional Lambda configuration the serving layer combines:
- A batch view (accurate but slightly stale)
- A real-time view (fresh but eventually corrected)
The merger can be carried out at the time of the query (by combining two stores) or by periodically incorporating the stream results into the batch results.
How data flows through a Lambda system
A simple end-to-end flow looks like this:
- The collection of events takes place by obtaining data from applications (such as clicks, purchases, and sensor readings) and then recording it in a durable log before storing it in an immutable raw store.
- With batch processing, jobs that are scheduled to run on a hourly or daily basis process the entire dataset in order to produce the ‘golden’ aggregates—such as daily revenue and customer lifetime value and product conversion rates.
- With regard to stream processing, the streaming jobs also calculate the same metrics for the most recent window—whether that is the last five minutes or the last hour—so that the dashboards remain up to date.
- When handling a query, the system first reads the batch results for most of the timeline before adding the streaming results for the most recent slice. Users will see the up-to-date figures now and the corrected figures at a later time.
Lambda is frequently described as “batch plus stream with reconciliation”. A typical example when people are doing a portfolio project alongside data science courses in Bangalore is an e-commerce analytics dashboard on which “today’s revenue” is updated in real time but the final figures are recalculated overnight to ensure accuracy.
Practical design choices and common pitfalls
Although Lambda Architecture is powerful it does add complexity and these are the problems that teams usually encounter:
Duplicate business logic
You could find yourself carrying out the same computation twice—first in batch mode and once in a streaming setup. This kind of duplication raises the amount of work involved in maintenance and leads to drift, that is, when the two processes differ.
To reduce the problem, make the transformations modular, share the validation logic, and ensure that the definitions (for example, the meaning of an ‘active user’) are the same in both layers.
Data quality, late events, and corrections
When deciding how to deal with late events and duplicates, streaming paths must take action because otherwise the dashboards may give a misleading impression.
To mitigate this, event-time processing should be used when it’s possible, idempotent writes or dedup keys should be applied, and the batch layer should be relied upon to “correct the record.”
Schema evolution and versioning
Real systems change over time. People add fields, change how events work, and update definitions.
To mitigate this, version events, enforce schema contracts, and ensure that the raw data remains immutable so that it can be replayed.
Serving performance
The layer responsible for serving must allow for quick reads (taking less than a second) and provide consistent costs.
Measures to take include pre-aggregating as much as possible, using a storage method that matches query patterns, and testing with realistic workloads.
When to use Lambda vs modern alternatives
Lambda shines when:
- You need both low latency and high accuracy
- You expect frequent backfills or logic changes
- Historical recomputation is a core requirement (compliance, audits)
Many modern teams do, in fact, opt for alternatives such as ‘stream-first’ designs (typically referred to as Kappa-style), involving the use of a single streaming pipeline through which the historical data is replayed using the same processing logic. While this approach can help to reduce duplication, it does so only if mature streaming operations are in place and if the reprocessing is carefully managed.
In reality, Lambda continues to be a useful mental model even if you never put it into literal practice. It teaches you to distinguish between “truth” (recomputable batch) and “freshness” (incremental stream), a pattern that often appears in production analytics. This kind of architectural thinking is precisely what makes data science courses in Bangalore more worthwhile for learners who hope to go beyond modelling and deal with actual deployment constraints.
Conclusion
Lambda Architecture is designed to meet a genuine operational requirement by providing accurate historical insights while at the same time reacting to events in near real time; it achieves this by dividing the processing into batch and speed layers and then bringing these together in a serving layer, thus offering a straightforward method of balancing correctness, latency, and the need for reprocessing. The principal drawback of Lambda Architecture is its complexity—particularly the need for duplicated logic—so it should be adopted with care and under proper governance. For those who are developing modern analytics systems, a understanding of Lambda is a good foundation, regardless of whether one comes across it directly in the course of work or through data science classes in Bangalore.