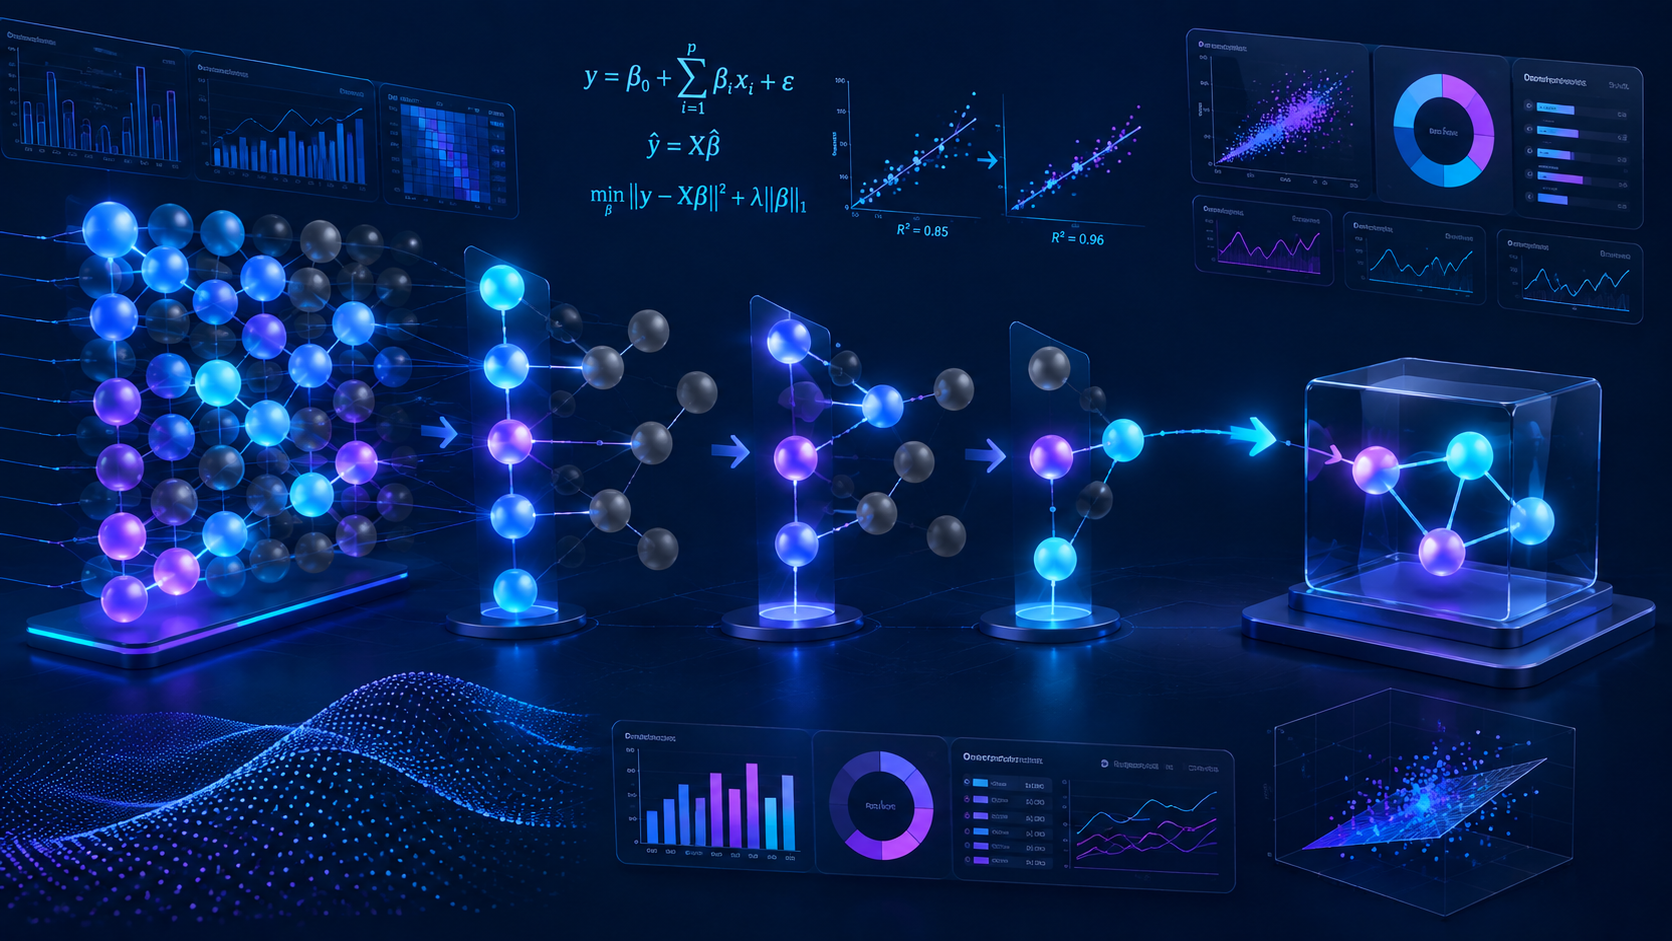
A basic and practical question when constructing a predictive model is this: which variables should I use? Including too few variables may mean missing out on important signals, while including too many can cause the model to become unstable, more difficult to explain, and more prone to overfitting. Stepwise regression is a well-known, automated method of variable selection which involves adding or removing predictors in a systematic way, according to a rule that aims to improve the model at each step. For people who are studying data analytics in Hyderabad, stepwise regression is usually presented as a link between the approach of “including all variables” and more up-to-date regularisation techniques.
What Stepwise Regression Does
Stepwise regression is not one algorithm but rather a group of procedures which repeatedly look for a useful set of predictor variables. Generally, the aim is to obtain a model that achieves a balance between fit and simplicity, and it does so by testing the candidate variables one at a time before deciding whether to include them or eliminate them.
There are three common variants:
Forward Selection
- Begin with no predictors (or with only those control variables which you have to include).
- The variable which has the greatest positive effect on the model should be added.
- Keep adding variables until none of the remaining ones gives a useful improvement.
Backward Elimination
- Begin with all of the candidate predictors.
- Take the variable that is of the least use (on the basis of a rule).
- Keep removing the variables until the ones that are left satisfy the rule.
Bidirectional Stepwise (Both Directions)
- It uses both forward and backward logic.
- It might remove a variable that seems no longer useful once a variable has been added when the model changes.
In actual projects analysts apply stepwise methods in order to reduce the large number of possible variables—particularly when there are dozens of operational metrics, customer attributes, or product signals and a quick baseline is required.
How “Best” Is Defined
To carry out stepwise regression it is necessary to have a criterion by which to judge whether a change represents an improvement. Among the usual options are:
- Add the variables which have coefficients that are statistically significant and eliminate those that are not significant.
- The adjusted R squared value (in the case of linear regression) improves the fit of the model but imposes a penalty when unnecessary predictors are included.
- The AIC (Akaike Information Criterion) penalizes complexity and the better the result the lower the AIC.
- The Bayesian Information Criterion (BIC) imposes a heavier penalty for complexity than does the AIC and as a result tends to select smaller models.
- In cases where cross-validation is used (which is preferred in many practical situations), select the model that shows the best performance on new data.
An important point is that a variable may appear “significant” in one step but later turn out to be unimportant because of its correlation with other variables; this is the reason why the selection path will differ according to whether you use a forward, backward, or bidirectional search.
Where Stepwise Regression Helps in Practice
Stepwise regression can be useful when:
- You should have a baseline model that is both quick to understand and easy to interpret for use in discussions with stakeholders.
- You have a number of possible predictors but are short on time for carrying out manual feature selection.
- You would like the feature set to be smaller so as to make reporting, monitoring, or the data pipelines simpler.
- You are currently using traditional regression methods and require an explanation based on coefficients.
For instance, suppose you are working with a subscription business that wants to predict churn. In this case, you could have various factors such as the number of support tickets, how often customers log in, the length of time since their last activity, the type of plan, whether discounts have been used, and the number of payment failures. Stepwise regression can be used to find a concise subset of variables that reasonably well explains the churn risk before progressing on to more sophisticated modelling. This type of approach is commonly followed in data analytics courses in Hyderabad since it enables both the building of models and disciplined variable selection.
Limitations You Must Understand
Stepwise regression is convenient, but it comes with important caveats:
- The possibility of overfitting lies in the fact that variables can be favoured merely because of random patterns, particularly when the dataset is small.
- Instability: Even minor changes to the data can cause different variables to be selected, especially in the case of correlated predictors.
- Due to bias in inference, p-values and confidence intervals become less reliable since the model was based on the same data.
- Confusion about multicollinearity: if the predictors are moving together (for example, ‘website visits’ and ‘time on site’), then stepwise methods might arbitrarily choose one or keep switching between them.
- A variable could be important in an operational sense even if it has only a small effect on a metric.
Since these limitations exist, stepwise regression should generally be regarded as an initial approach rather than as the final answer.
A Practical, Safer Workflow
If you do use stepwise regression, these steps reduce risk:
- Define the candidate pool carefully
- Erase any variables that are duplicates, leaky (since they contain information about the future), or irrelevant.
- Split data properly
- It is necessary to use a validation set (or carry out cross-validation), and the choice should be based on out-of-sample performance rather than just on in-sample metrics.
- Choose a criterion aligned to your goal
- If interpretability is important, BIC or cross-validation usually leads to simpler models.
- Check diagnostics after selection
- Look at the residual patterns, the signs of the coefficients, the presence of multicollinearity (for example, as measured by the VIF), and check whether the results make sense from a business point of view.
- Compare with alternatives
- Attempt the use of LASSO/Elastic Net (regularisation), tree-based models, or feature selection based on the specific domain. If these methods consistently give better results than stepwise methods, then go with them.
This disciplined approach is emphasised in well-structured data analytics courses in Hyderabad, because it mirrors how variable selection is handled in real analytics teams: quick baselines first, then stronger validation and model comparison.
Conclusion
Stepwise regression offers an automated way to select variables by iteratively adding and/or removing predictors based on a chosen criterion. It can create compact, interpretable models quickly—useful for baselines and early insights. However, it can be unstable and can overfit if you rely only on in-sample statistics. The best practice is to treat stepwise regression as a tool for narrowing options, validate results on unseen data, and compare against regularisation methods and domain-informed selection. Used carefully, it remains a valuable technique in the modelling toolkit.